Timestamps follow the original livestream. Select a time to watch that moment. Transcripts are machine-generated with reviewed name and terminology corrections; occasional recognition errors may remain.
1:55:23I'm part of the Wells Fargo team.
1:55:25I'm leading the Frontier AI modeling organization here.
1:55:29And I'm going to show you the work we've been doing lastly on building our first foundation
1:55:34model, Wells Fargo Foundation model.
1:55:37So I explain why we did that, how we did it, and what we accomplished.
1:55:41in doing so so so first from financial model it doesn't necessarily need to be language based i
1:55:48mean we're all playing with uh claude and chat gpt and others they're all language-based
1:55:55from the show models in financial services uh we also have language of course uh from a
1:56:00structure unstructured representation data but we also have a lot of structure representation
1:56:05a lot of these data is tabular data we have a lot of information from our customers we have
1:56:11information in investment banking, consumer banking, and all of this data is data that we
1:56:17have in Wells Fargo, and all big financial organizations have too. And we want to take
1:56:23benefit of all of this huge amount of data that we have. And it's not like you just take it and
1:56:30put it in a language model and get the best of it. Of course, you can get a lot of benefit out of it,
1:56:37but it's not necessarily the best way to do it.
1:56:40So what we decided to do is to look at the data we have,
1:56:43all the transactions, all the customer transactions
1:56:46that they're doing with their debit card, credit card, digital, check,
1:56:50all of those coming from many different channels
1:56:52and see if we can build a foundational model
1:56:56that we can use and fine-tune for downstream tasks
1:56:59like credit scoring or that you can use it for fraud detection,
1:57:03anti-money laundering, do marketing.
1:57:05So how we can build one backbone that you can use and streamline across downstream tasks.
1:57:12So now you're moving from many models very siloed across different organizations.
1:57:17In really one backbone that every organization can just reuse because you learn the representations of customers' transactions at scale.
1:57:28And just spoiler alert, you may say, hey, that's tabular data.
1:57:31why do you just don't use XGBoost and the usual suspect?
1:57:36This is the model we had in production.
1:57:37But the model I'm going to show you is something that beats XGBoost,
1:57:42even from a latency perspective, but also from a fault detection,
1:57:47we get much better reduction of false positive and better detection rate.
1:57:54So it was a really good lesson learned in terms of having better model
1:58:01And to foundation, I mean transformer blocks, and that's what we build.
1:58:06So we have, as I mentioned, billions of transactions on a monthly basis.
1:58:13Our customers are interacting with their debit credit card, and they do checks, and they do different sort of transactions.
1:58:19And the question is really how we can use this information at scale, and not for one and every single downstream task.
1:58:26So I'm going to cover a bit of the data, the representations, the architecture that we use,
1:58:34what the result we get, and the lesson we learned in building this.
1:58:40So left-hand side, language foundational model.
1:58:44They're processing language tokens, and then the goal is to learn the representations that's going to predict the next token.
1:58:51and then you have supervised fine-tuning
1:58:57and all of the great post-training process
1:59:00to get better at the task that you want to, right?
1:59:03And that's for languages, that's great.
1:59:05But what if your data is very much more specialized
1:59:11So that's where we build this transaction foundation model.
1:59:15So instead of having languages as the base,
1:59:19the base is now transactions.
1:59:21transaction from our customers.
1:59:23And you still try to predict the next thing,
1:59:26and here the next thing is the next transaction,
1:59:28or it's the next token in the transaction,
1:59:30using all of the channels that you have.
1:59:32But that's not the end goal.
1:59:34I mean, similarly to language model,
1:59:36where you try to predict the next token,
1:59:38that's not the end of the story, right?
1:59:40You learn the representation,
1:59:41and then you use that representation,
1:59:45and you post-tune it for any other task, right?
1:59:48So it could be classification tasks for languages,
1:59:50but in our context for transaction foundation model it could be used for
1:59:54credit line increase could be used for doing fraud detections and flagging
2:00:00an anti-money-laundering perspective.
2:00:01And the goal is to learn this relationship between transactions over time and transactions across customers. That's really the intent.
2:00:10So the intent number one is you do pre-train from scratch. I'm saying it again because people are sometimes confused.
2:00:17we pre-train transformer blocks at scale from scratch using our transaction data.
2:00:26So the zero rate that we use from open rates, we just use the architecture,
2:00:30and then we pre-train it from scratch using our GPU cluster,
2:00:34and then we train it for a couple of days and weeks,
2:00:38and then you do the downstream task of post-training.
2:00:42but the goal here and you pre-train it
2:00:47token or the next transactions
2:00:50you try to predict the next pattern
2:00:52of the customer but that's not the intent
2:00:54the intent is to do the downstream
2:00:56task later on and in terms of scale
2:01:02so we have billions of transactions
2:01:11basis interacting with their
2:01:12debit card, credit card, or doing check.
2:01:15And the five main dimensions we look at
2:01:20I mean, who is processing and who is asking
2:01:23and who is providing a service.
2:01:25So, will it the customer or the merchant?
2:01:40And all of those, they're basically breaking down in hundreds of features.
2:01:44And if you look at the existing model we have in production,
2:01:48there's a lot of people that build those models in similar organizations
2:01:56They build a lot of very hard-crafted, uncrafted engineering,
2:02:01feature engineering efforts on that.
2:02:03And that's required a lot and a lot of time.
2:02:05So we step back and look at the raw features we need,
2:02:08not the one that's been pre-built and post-built for doing the downstream tasks,
2:02:14but try to understand which raw features.
2:02:16And we ended up with basically Android features.
2:02:19Even at the end of the day, we had thousands of them,
2:02:22but we tried to find which ones are the raw information unit.
2:02:27And then we led the architecture, the transformer blocks,
2:02:31to figure out the relationship between those core features.
2:02:36we do have a bunch of features
2:02:41and the vocabulary is very unique
2:02:44to the financial services setup
2:02:53because the vocabulary that we use
2:02:56is very specific to the work
2:03:02while all digital and checking and saving
2:03:06and all of those sort of transactions,
2:03:10even if you merge all of those,
2:03:12you still end up with a very limited number of features and characteristics.
2:03:15So at that scale, then the question is,
2:03:18well, how you work with that?
2:03:20So we started, everything is tabular data.
2:03:23I mean, there's no secret, it's tabular data.
2:03:25And then the goal is to understand
2:03:26how you're going to capture the vocabulary
2:03:29because you do have numerical values,
2:03:31you have categorical values, you have information like zip code,
2:03:37do you encode each and every zip code in a token?
2:03:41So there's a lot of efforts you need to push in understanding
2:03:44the vocabulary that you need and the vocabulary that you want also to scale
2:03:49because at the training, if you have too huge vocabulary,
2:03:52it would be kind of messy to train such a model with a vocabulary
2:03:57So there's a lot of effort in understanding this value to tokens.
2:04:02So which information do you encode in a token?
2:04:04And then you have the token to ID, the tokenizations,
2:04:07and then the embedding lookup.
2:04:09So then when we have a transaction coming up,
2:04:13So basically it's a lookup in aligning a transaction
2:04:16and all the characteristics of that transaction
2:04:19to a token and an ID and then an embedding.
2:04:25So just to give you a number,
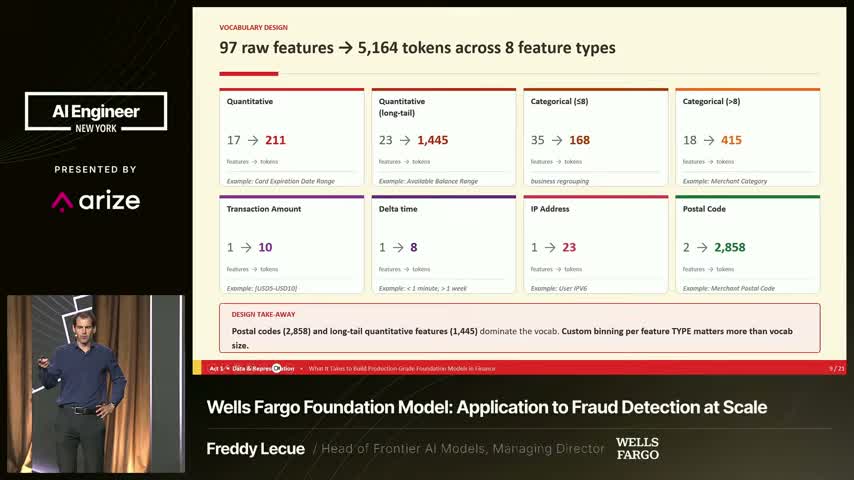
2:04:26well some numbers so we have quantitative qualitative categorical of different kind
2:04:32right so categories with only eight types some with much bigger types you have transaction amount
2:04:38which is a big deal you have the delta time between transaction so you have anything related
2:04:44to ip address postal code so just to give you example of variety and heterogeneity of each and
2:04:51every characteristic could be encoded in a binary token
2:04:55or could be encoded in a much larger number of tokens.
2:04:59And even if you look at the zip code,
2:05:01I mean, you have a much larger number of zip code
2:05:07but you have much better way to structure
2:05:11how you're going to regroup zip code
2:05:15based on distributions, for instance.
2:05:31no clue how it's going to work in the tabular
2:05:37open ways and open solutions
2:05:45what they learn and adapt it to what we needed to do and that gives you an
2:05:49example of invading dimensions number of decoder blocks we use and all of the
2:05:54recipe from a from an architecture perspective so we have and as you can
2:06:00see we're not trying to build a trillion parameters model we don't try to compete
2:06:05with any of the the leaders in the language models because we working with
2:06:11and focusing on transactions, right?
2:06:14Transactions, foundation models at billion level.
2:06:18And one billion is because that's the model that gave us,
2:06:21that was kind of the smallest and gave us the highest boost.
2:06:25And now we're working on the next versions at 11 billion.
2:06:29But that's good enough to give a lot of ROI
2:06:33from a false positive reduction for downstream tasks
2:06:37like for detections and the detection,
2:06:41So, and the type of architecture,
2:06:45so the decoder-only architecture,
2:06:47that's basically for predicting the next token
2:06:51And that's really the pre-training.
2:06:54So here we initially used 20 times the number of parameters
2:06:57to define the number of tokens we might need.
2:06:59We ended up actually 10 times fractured than that.
2:07:02So by doing a few experimentations,
2:07:04we needed much more tokens per parameters.
2:07:08I mean, this is kind of the initial experimentation we did.
2:07:13So I'll pass on this because this is the usual suspect
2:07:19so causal language modeling and mass language modeling
2:07:27And from an architecture perspective,
2:07:33the most complex part was really the tokenization
2:07:37doing the pre-training and then how you do the fine-tuning.
2:07:41So I would say the recipe or the secret sauce
2:07:43is really how you do the tokenization
2:07:45and how you're going to do the post-training.
2:07:48But anything from a training perspective,
2:07:56you're going to put in your context
2:07:58or in your history for doing the training.
2:08:00and evaluation perplexity-based accuracy dashboard
2:08:09And so, yeah, so use mixed precision,
2:08:25and memory efficiency, flash attention,
2:08:28I mean, here there's nothing really new.
2:08:30It's just we use the advices from the best
2:08:35and from the one that built even much bigger models.
2:08:42But I wanted to spend some time on the results.
2:08:47So, yeah, so when you build this foundation,
2:08:52That foundation is really, is only a backbone.
2:08:58It's something you can use for downstream tasks.
2:09:01And the downstream task was to do fraud classification.
2:09:04So you have a transaction, and then you try to predict if that transaction is going to be fraudulent.
2:09:09So in the model we have in production, it's an XGBoost model,
2:09:13and it's trained on large amount of transactions, which is fraudulent or non-fraudulent.
2:09:23between whatever transaction
2:09:25you try to predict, try to classify
2:09:28and the relationship with this
2:09:29transaction with all of the past transactions
2:09:32and that information is kind of
2:09:34gone when you use an XGBoost model
2:09:38in a very hard way which is not
2:09:41transformer architectures you do have
2:09:48And that's basically what helps, and this is what we think, this is what really helps pushing the fraud detection rate much higher.
2:09:56But at the end of the day, the downstream task was to say, here's the
2:10:00sequence of transactions. I have someone just using the debit card. Is that transaction fraudulent with respect of all historical information? And that's exactly what you put in at inference time when you try to do the prediction.
2:10:21really fancier you just need to have the
2:10:28milliseconds for doing the processing
2:10:32decline needed to happen within that time frame
2:10:3810 times slower than done from a latency perspective
2:10:44final result we get. So the main
2:10:56and false positive rate. Of course
2:10:58you can detect much higher, but
2:11:02sometimes you get much more false positive.
2:11:04And in this case, we managed to get
2:11:13because at the end of the day
2:11:15if you decline a transaction
2:11:19then that person is going to call
2:11:21there is an operation cost associated to it
2:11:23you lose the transaction related to
2:11:31something that you don't really want to happen
2:11:35that's compared to the state of the art
2:11:44It's millions of dollars savings.
2:11:50So just to finish up on that slide,
2:11:53so that foundation model has been built on billions of transactions
2:12:06It's pre-trained from scratch.
2:12:08So we don't free train from any open-rate existing model.
2:12:11We use existing architecture, but the way the zero rate, we pre-training on a couple
2:12:18I mean, we did a couple of weeks initially, but then that's pre-trained.
2:12:21And then when it's pre-trained, it's pretty good in predicting the next transaction.
2:12:26And when you're done with that, then you can use it for many downstream tasks.
2:12:29We did it for fraud detection.
2:12:31Now we're investigating for credit line increase, investigating for anti-money laundering,
2:12:36investigating for marketing.
2:12:37so now the same foundation is used
2:12:39across different organizations
2:12:45thank you for having me and thank you
No passages match. Try a shorter word or phrase.