Timestamps follow the original livestream. Select a time to watch that moment. Transcripts are machine-generated with reviewed name and terminology corrections; occasional recognition errors may remain.
7:28:58I want you to zoom out for a second and think about if somebody were to tell you today that
7:29:05we would take all the information on the internet and then we would train a model on it and
7:29:11we would use that in order to solve scientific problems that were not on the internet.
7:29:15I think a lot of people would tell you that that's crazy.
7:29:20And what we're doing has a lot of parallels to that story.
7:29:25So if you think about how intelligence works, imagine for a second that you're in the movie
7:29:31Frozen and you're Olaf, the snowman.
7:29:36If Olaf was an LLM, and there's a scene which is one of my favorites, which is where he rolls
7:29:42down a mountain and there's a little stone that pops up and Olaf spreads out, temporarily
7:29:49becomes a disassembled snowman and then becomes an assembled snowman.
7:29:52Olaf knows how to do that because Olaf can observe as he is acting.
7:30:00LLMs, which autoregressively predict tokens, constantly part of that behavior is that it's constantly observing as it is acting.
7:30:10And so this is the big difference between, you know, when you see LLMs try to solve robotics problems or when you look at native architectures like we're working on, it's very, very easy to think of LLMs in the demos to see on Twitter as the thing that will
7:30:24Solve everything, there are fundamental limitations where purpose-built models are a much better
7:30:31Today I'm going to talk a little bit about what the other side of that coin looks like.
7:30:38For us, it all started with Medal.
7:30:40We built the largest video game recorder in the world, and we think of that as the internet.
7:30:47People use Medal to record themselves playing tens of thousands of different video games,
7:30:51And if you think about it, as a human, we can teleoperate a robot with the exact same
7:31:00brain that we played at video game, and in fact, in many cases, we also can use the same
7:31:10So what this means is that the action space of video games, often because of game controllers,
7:31:14and the action space of teleoperations or the real world, in many cases is the same.
7:31:19And so every single robot, below certain degrees of freedom, ships with the game controller.
7:31:25The majority of the supply chains already work this way.
7:31:27And so we thought, what if you just take all of the action data that we get through the
7:31:32video recorder, which associates the inputs and the actions with the actual frames, we
7:31:38label the actions so we understand semantic meaning behind every action, and we use it
7:31:43to give it to a vision-based model.
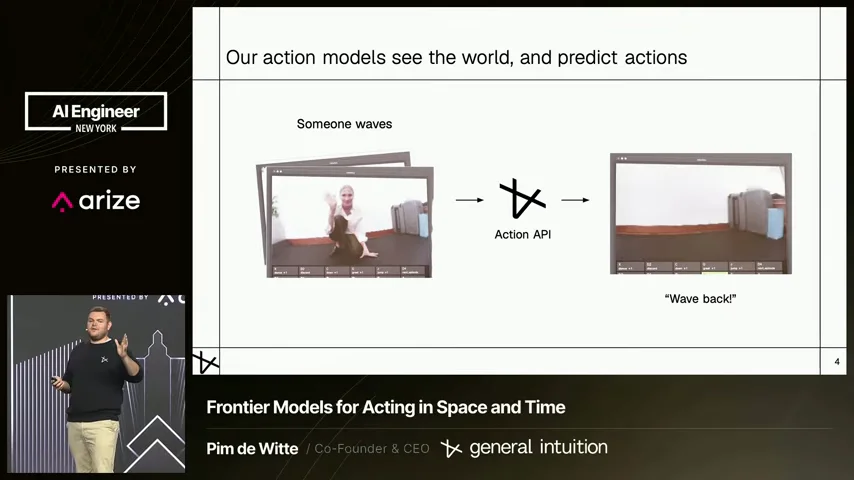
7:31:46What you see here on the left is just an intuitive way of how the model works.
7:31:51You give the model a set of keys to choose from, essentially a computer use model.
7:31:56It gives frames as the input, so you can give it a text prompt as well.
7:32:00And you send it through API, and you say somebody waves at you, wave back.
7:32:05In the input space, the model understands that you have a grid action available, it
7:32:08will output the action associated with that.
7:32:12One way of intuitive understanding how this works, I've obviously simplified here because
7:32:18it's predicting the next token, not the next word, but bear with me here.
7:32:23LLMs took large-scale internet data, then trained it to predict the next text token,
7:32:28and now use it for writing software.
7:32:31These are all workloads that are really, really well fit for futures that are not simultaneously
7:32:36unfolding as you are predicting.
7:32:40You can say something, the model will do something, you can say something again, the model will
7:32:46And you can use it for lots of valuable work, but at the end of the day, because it's turn-based,
7:32:52it's very, very difficult for it to generalize to environments, especially that include space
7:32:59So our models, the way that they work is they're continuously receiving frames or receiving
7:33:07batches of information from the camera of the robot, or it could be a screen.
7:33:12And it predicts everything as if it were just a video game.
7:33:18So you can think of the way that Anthropic focused on just nailing coding.
7:33:23So they were never frontier and just base text generation.
7:33:27They always focused on being the best at generating code.
7:33:30And then the bet that they made is that more people would start bringing more problems
7:33:34If you think of general intuition, our bet is that you can, as humans, we are generally pixel-to-action converters, plus senses, which in many cases you can convert into pixels as well.
7:33:46And you can output actions at the same time.
7:33:50Those actions are, in this case, either keyboard and mouse or game controller.
7:33:53So the output tokens of the model are essentially equivalent to that of enhanced computer use model with more actions on the output space to internalize it.
7:34:01So you send frames, and you get actions.
7:34:04This works, again, because every single thing that you see here can control all of these different embodiments.
7:34:11So, as humans, we do not know how to predict motor torque.
7:34:21We do not know what value to send to a machine.
7:34:25There's this beautiful device that has been made for many years, which actually does that work for us so we can control them.
7:34:32Most robotics companies today are trying to solve the problem at the end-to-end level,
7:34:37trying to predict exact poses or exact values in the motor,
7:34:42instead of just looking and picking up the thing that every robotics company has built
7:34:50to generalize our very limited abilities to have physics understanding and predict exact values,
7:35:00And so our approach is, let's just use that.
7:35:05And so Medal, at the moment, sees about a billion videos uploaded per year.
7:35:12This year we're on track for three billion,
7:35:15which lead to over a trillion and a half action tokens per month.
7:35:20So just for comparison, to think about the bet,
7:35:23the total amount of data that Frontier Labs use today to train robotics models,
7:35:26we collect in, at the moment, half a day.
7:35:29And so the type of bet, and again, think of the fact that humans can use the exact same
7:35:38controllers and their eyes to play video games that they can't help upgrade robots.
7:35:44We just bet on scaling pixel space the same way that anthropics killed coding space, and
7:35:50betting that people will just, as we scale data compute into pixel space, that people
7:35:54will bring more problems into pixel space.
7:36:01of a sudden you get an incredibly general agent that can go and solve problems on computers
7:36:14in addition, similarly to how Anthropic focuses on doing coding environments, we focus
7:36:20on world models, which most of you know is for, the Mirai release world models, to then
7:36:25generate additional environments for these models to learn in.
7:36:27One way of internalizing a big advantage of this approach against LLMs is if you're an
7:36:34LLM company and you have to bet on the ability to generate environments for your models to
7:36:39learn, you have two problems.
7:36:41One, you actually need to spend the compute to simulate environments, and the more realistic
7:36:45you try to simulate, the more expensive that gets.
7:36:48and so imagine you want to learn a new thing
7:36:51you want to learn that new thing
7:36:53in the exact input space of the human
7:36:57so if we are learning from pixels
7:37:00we're learning by looking around
7:37:01if I'm trying to communicate something
7:37:03I want my robot partner to observe that exact same thing
7:37:11is for that to have to go through an LM
7:37:13for a digital twin to have to be created
7:37:14for the model to have to get deployed
7:37:16for it to be a bunch of verifier checks
7:37:18whether or not things are equivalent
7:37:20and then for the robot to learn much later.
7:37:22And so one way of thinking about it is
7:37:24when you can learn in the native modality of the human,
7:37:27you can all of a sudden start solving a lot more problems
7:37:32What you'll see when these models come out
7:37:33is they're significantly faster than any LLM
7:37:42Because games are so action-dense,
7:37:44So what you see, right, is one thing that's interesting is you saw, for instance, the model predicting multiple actions at the same time.
7:37:52We're able to take that action density from gamers and convert them into really complex robotics workloads.
7:37:59So, for example, if you are operating a drone and you need to make lots of little adjustments, you really, really, really want to start with games.
7:38:06You don't want to start with teleoperations because the human will just take a lot less actions.
7:38:11It has a lot less information.
7:38:12You want a model that can predict really high APM.
7:38:16And so the APM of the data set puts a lot of these problems all of a sudden in reach
7:38:21so that it can do a lot of these actions simultaneously.
7:38:24And as I mentioned, the model doesn't just understand the key it's predicting.
7:38:28It also understands the semantic meaning associated with that key it's predicting, which is really
7:38:31important for things like interpretability.
7:38:37So we will be releasing the models this year.
7:38:43I think the correct word would be
7:38:47by the fact of what these models can do
7:38:53live stream so I unfortunately couldn't share
7:38:57breaking the surprise but if you're in New York
7:39:01we have started doing a few demos
7:39:05know somebody on the team reach out and we can start
7:39:07It's showing you some of the capabilities live.
7:39:11But we have essentially one model which can play video games at the highest level
7:39:14and control over 10 types of robots using the exact same primitives.
7:39:20So pixels in, actions out, completely real time.
7:39:23And we'll be rolling out early access to these models over the next few months.
7:39:28We already have some customers that are on them, but it's still private,
7:39:32so you're not hearing too much about it.
7:39:33But if you scan this QR code, you'll be able to get the models because we go by who signs
7:39:42up on the wait list at which times.
7:39:44So this is a great moment to get in touch.
7:39:47As I mentioned, we are in New York.
7:39:48What you'll find is similar to how Jev and a lot of these decision-making models have
7:39:55kind of opened people's eyes on what you can do when you have a new architectural primitive.
7:40:00to do away with the unpredictability of an LLM and put something in that is more reliable and faster and you understand how it is going to react as opposed to having to work around it.
7:40:10If that resonates, these models are exactly what you're looking for. And all of a sudden you can start exploring the environments that you generate with LLMs.
7:40:21All of a sudden, one of the use cases that I'm really, really excited about is, well,
7:40:26these models, they can take actions as if a human was on the interface.
7:40:31And so if you're doing UX work and you're trying to understand, is this an intuitive
7:40:36Well, this is a very interesting way of solving the problem.
7:40:38So all these problems that LLMs can't solve because they can't actually explore like a
7:40:42human, you can use these problems and start using these models for.
7:40:48So the way that they're going to be released is we still expect you to use an orchestrator model.
7:40:54So you may use something like Gemini or Astra in order to do long-term planning and everything.
7:40:59And you'll be able to plug these into your workloads.
7:41:02And we're actually, the models are so general.
7:41:05It is genuinely going to, I think, feel like the early LLM days when you have a new toy
7:41:12and you just want to figure out what it does and all the things you can use it for.
7:41:18when I first started using the checkpoints
7:41:21and I think you'll have the same reaction
7:41:24and I think a lot of you will
7:41:28if you're a bit early and you start understanding these primitives
7:41:33that you can even build lots of businesses on top of this
7:41:43all of a sudden if you can reliably
7:41:44orchestrate robots in space and time, and they can take text instructions and do things.
7:41:50All of a sudden, it's a recursive problem, right?
7:41:55Robotics is interesting because one of the big problems of solving robotics is making
7:41:59And so there are all these businesses that, because it's so bottlenecked by intelligence,
7:42:04are going to emerge just from solving this one simple problem, which is pixels to actions.
7:42:10And I think if you're early on getting your hands on these, it will have a similar effect
7:42:15on getting your hands on early LLMs.
7:42:20I am most excited also, one of the things that we're working on which is interesting
7:42:26is if you have any friends or family who are in some way need accessibility help for using
7:42:34their computer, because these models can use computers like a human, all of a sudden, for
7:42:37For instance, if you only can use one arm, all of a sudden the model can allow you to
7:42:43play video games because you can just control the mouse and the model is predicting the
7:42:51Because the model also understands which actions you're predicting, because that's the input,
7:42:55it's observing as it's acting, it will actually just not predict the things that you're doing
7:43:00and it will just predict the keys.
7:43:02It has all these downstream effects of things that you can build on top.
7:43:08If you're interested in building in this space, this is going to be the most interesting toy
7:43:18I also think a lot of the initial usage will sit in simulation.
7:43:21If a lot of you are into generating environments with Astra or Gemini, it's perfect.
7:43:25Now all of a sudden you can have something that can explore it and you don't have to
7:43:28itself, and it's perfect timing because of all the environment generation capabilities
7:43:38So really quickly before I wrap up, I want to talk about the team.
7:43:42We are based in New York City.
7:43:46The Medal team and the general intuition team is here in New York City, so if you're here
7:43:49you should reach out to us and we can both show you the models, especially if you want
7:43:55to join the team, I think we'll prioritize even higher.
7:44:00But we really are looking for people who, A,
7:44:05want to understand these models as much as we do.
7:44:08So if you're really, really good at generating
7:44:09novel environments, typically if you have some sort
7:44:12of research background, but I don't have a research
7:44:16If you come from an engineering background
7:44:18and you're very happy to learn, this is fine too.
7:44:22And ideally what we want is somebody who has experienced shipping end-to-end AI products,
7:44:32but it doesn't have to be on the research side.
7:44:33So we just want to hire people that understand the entire thing.
7:44:41So one is role modeling, the other is the policy, so the agent, and the other one is
7:44:46working on essentially the data generation and the environment generation.
7:44:50If you are an engineer, the best one to join is the environment generation team.
7:44:55And then you grow into getting access to everyone.
7:45:00I'm very, very excited for November.
7:45:02I really hope that you'll be on the lookout.
7:45:07As I mentioned, it will be either late November or early December is the current planning.
7:45:12We are going to organize three hackathons.
7:45:15The first is in New York City, it will be mid-November.
7:45:22If you sign up for the partner wait list, we will send out some emails so everybody
7:45:27We hope to see everybody at the hackathons.
7:45:30I think it will be the first time to get your hands on them the way we are playing with
7:45:35And there will be one in New York City and one in London.
7:45:37So if you are in either of those cities or want to travel to either of those cities,
7:45:40those would be good times to meet the team.
7:45:47I have time for one or two questions,
7:45:49and then I think we can wrap.
7:46:00How is it different from JEPA?
7:46:02Yeah, how is it different from JEPA?
7:46:04So JEPA doesn't train alongside the action labels,
7:46:06so they bet on inferred action labels for the most part,
7:46:09which I think, one of the ways of thinking about it
7:46:11is JEPA I think in the limit is the more correct approach
7:46:13but it's just a lot less practical in the short term
7:46:15because you need to bet on a separate
7:46:17scaling law on the action inference itself
7:46:23JEPA as a concept, we think it's a
7:46:26you know, we use some of the
7:46:30but at the end of the day it's an approach
7:46:32not a product and I think we'll
7:46:40one way of thinking about it is
7:46:43because we have so much action data
7:46:46let's say you're flying a plane
7:46:47and you're moving the rudder in the back
7:46:49there's no way of being able to
7:46:52tell that from the video frames
7:46:54so our mode on having the action data
7:46:59action sequences than it does
7:47:01to world models and to generating
7:47:05we just went all in on training these general
7:47:06foundation models for action predictions
7:47:08and we use all sorts of techniques to do world models.
7:47:12We really like other companies building them as well.
7:47:19One more and then I've got to run, I think.
No passages match. Try a shorter word or phrase.